unified-ai-runtime
One C API over QNN, ONNX Runtime, TFLite, CoreML, llama.cpp, TensorRT, OpenVINO and NCNN.
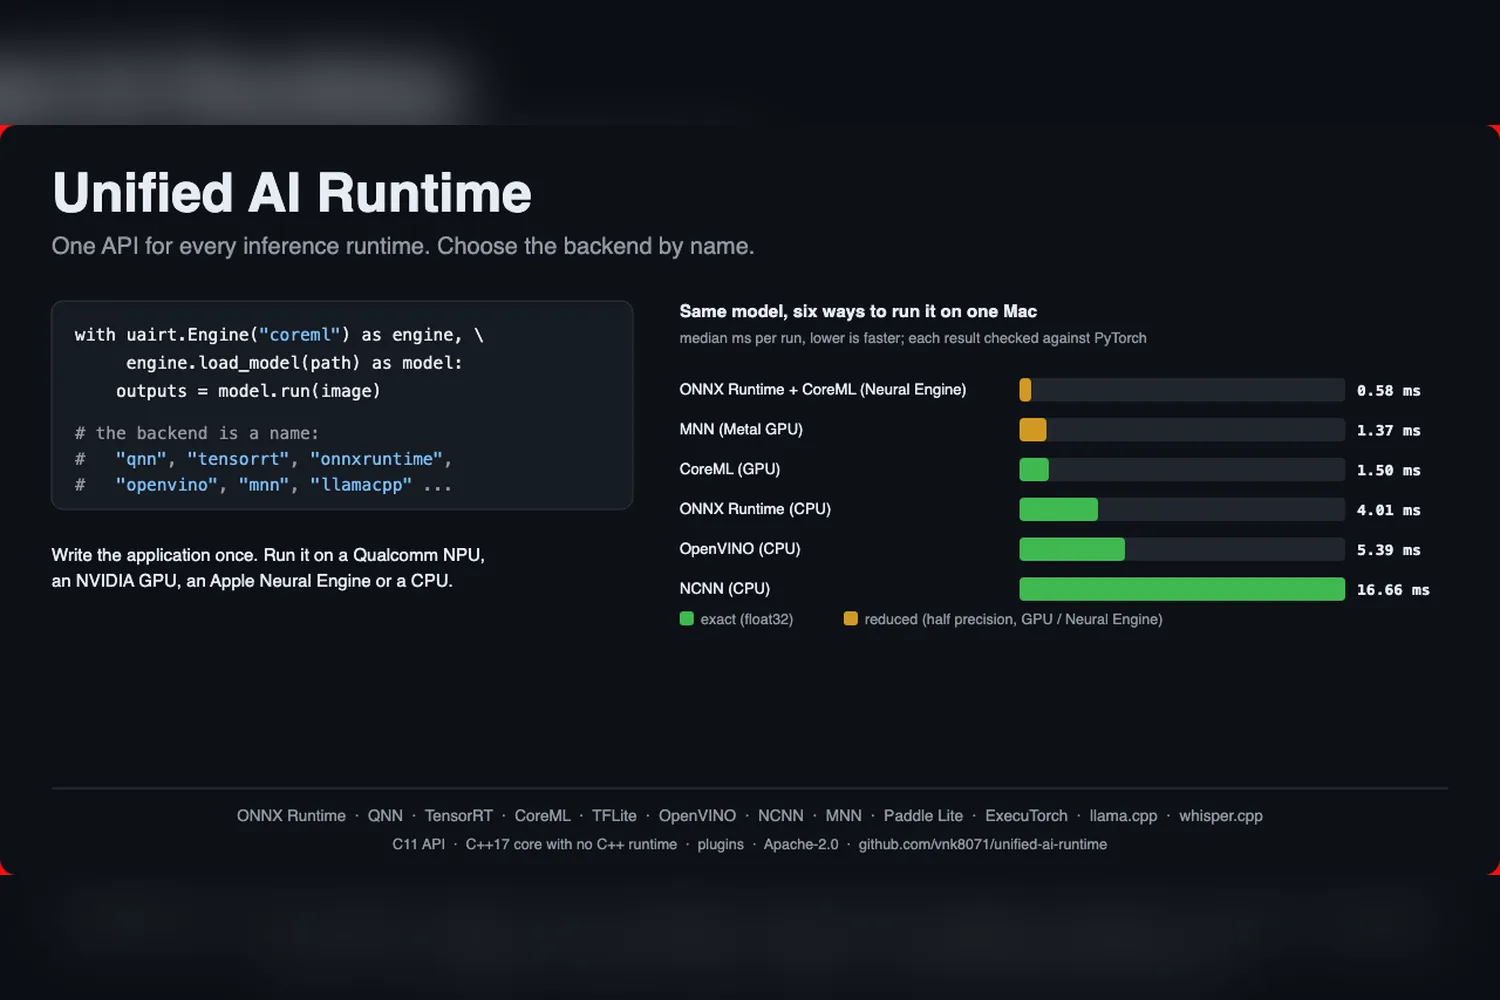
Write the application code once and choose the backend by name; a device or SDK mismatch returns an error instead of silently falling back to the CPU.
Role
Author
Year
2026
Stack
C, C++, Python
Published on PyPI as uairt; the source is on GitHub.
Unified AI Runtime (UAIRT) ⚙️
| Repo | PyPI |
One C API to run compiled AI models on QNN (Qualcomm NPUs), ONNX Runtime, TFLite, CoreML, llama.cpp (GGUF language models), TensorRT, OpenVINO and NCNN. Write the application code once; choose the backend by name when you create an engine.
 your app ──► uairt C API ──► one plugin per backend ──► the vendor's own runtime
                                 ├─ QNN                  (Qualcomm NPUs)
                                 ├─ ONNX Runtime · TFLite · CoreML
                                 ├─ llama.cpp            (GGUF language models; CUDA / Vulkan / OpenCL / Hexagon NPU)
                                 └─ TensorRT · OpenVINO · NCNN
UAIRT loads artifacts that each vendor’s toolchain already produced and runs them through that vendor’s runtime. It does not convert or quantize models, and a device or SDK mismatch returns an error instead of silently falling back to the CPU.
Highlights
- Plain C ABI with a plugin per backend, so other languages can bind to it
- Python bindings:
AutoModel.from_file("model.onnx", device="cpu") - Stateful session API for language models (
.gguf) with token streaming - llama.cpp device selection — CUDA, Vulkan, OpenCL, Hexagon NPU
- Verified against each vendor’s own tool on real hardware (Snapdragon, Apple M5, NVIDIA, Intel)
Tech stack
- Core: C / C++, CMake
- Bindings: Python (wheels on PyPI), Rust
- Backends: QNN, ONNX Runtime, TFLite, CoreML, llama.cpp, TensorRT, OpenVINO, NCNN
kilomet.com.vn
/2026
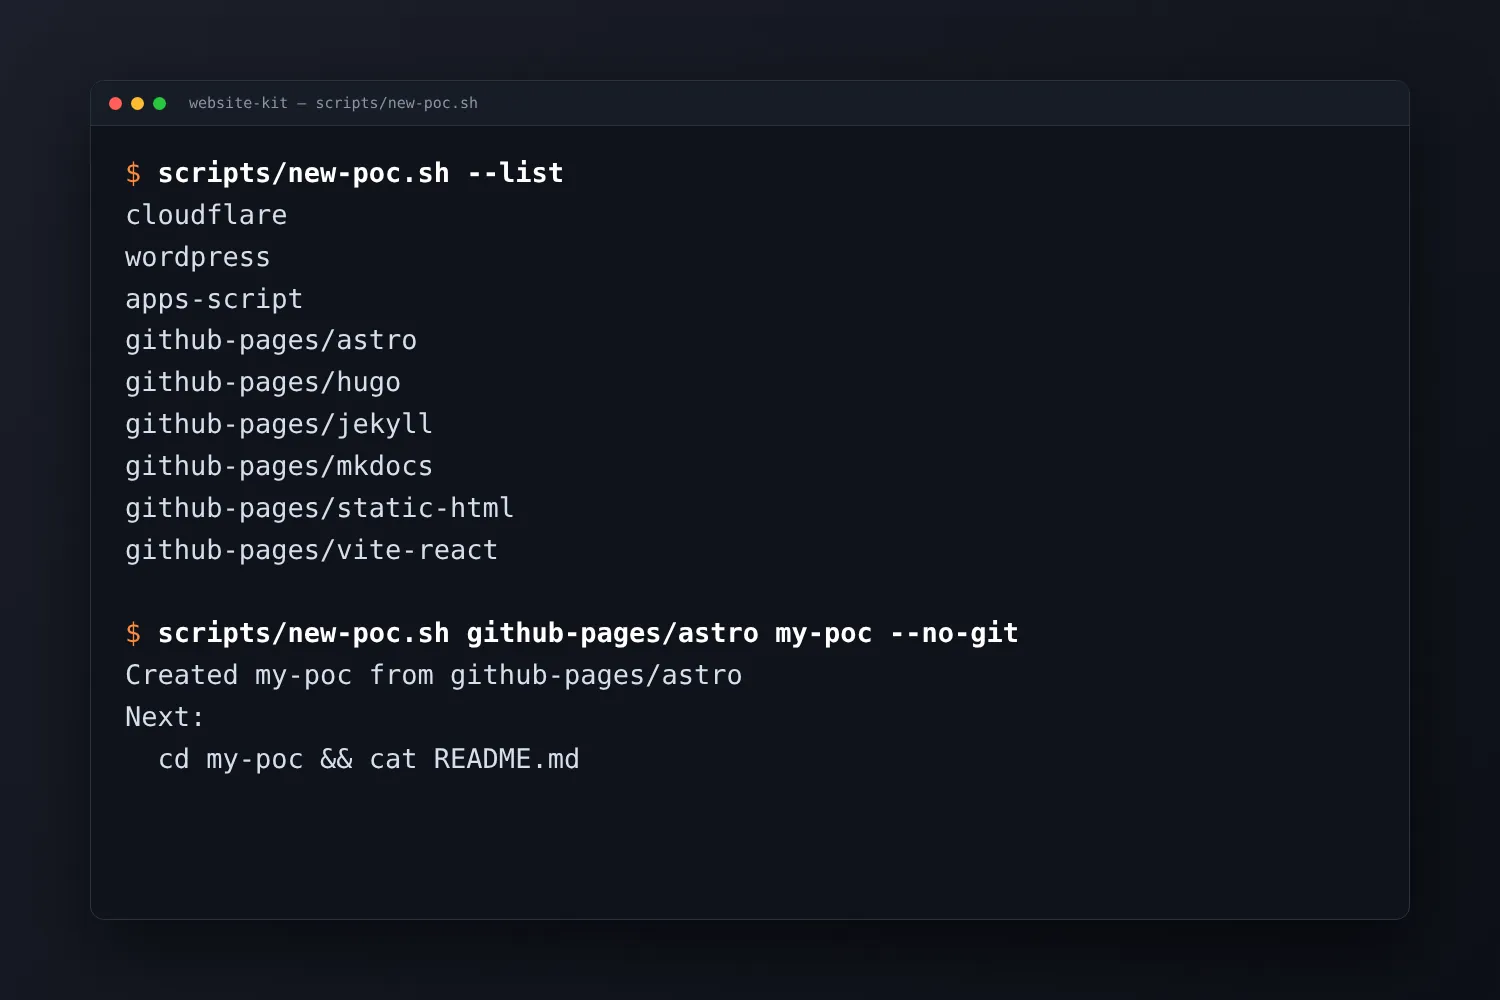
website-kit
/2026
Have a project in mind?
Let’s Talk
Let’s Talk
Email me